How Contentful built trust in Investigations, one incident at a time
Contentful is the digital experience platform behind thousands of products and websites. That makes reliability critical: customers depend on high uptime and low latency, and on peak days like Black Friday the platform serves billions of transactions.
3.4x faster median time to diagnose with Investigations
150 up from about 20 on-call responders
Half a day of setup per service replaced by sync
Industry
SaaS
Company size
Mid-Market
Use cases
Adopting AI in incident management, Faster root cause analysis, Legacy tool replacement
"Customers aren't just buying software. They're buying the reliability of our service, the uptime, the performance," says Eoin Crowley, VP of Engineering, whose group owns Contentful's infrastructure and incident response. "If we're down, they're down."
As Contentful scaled, incident response had to keep up. In the early days it was a best-effort process, and even as the company matured, much of it stayed manual. "You had real experts in that space, and then it was kind of left to them," Eoin says. Contentful fixed that in stages: first the incident process, then paging, and then AI that helps responders investigate.
Getting the basics right
Contentful didn't switch because something was broken. "Things were fine, our customers were happy," says Michael Pearce, Senior Engineering Manager for platform engineering and incident response. "It's hard to sell a business case to leadership when you’re trying to improve something that isn’t broken, even when it’s an opportunity to make a process much better.”
When Michael joined, incident response ran on homegrown Slack scripts, one shared channel and more than ten different monitoring tools. James Bourne, a Senior Software Engineer on the platform team and one of its on-call responders, remembers the old incident command well: "It sent a message to the incident channel that said, hey, there's an incident, grab your towel. That was all the help you got."
The turning point was a company-wide hackathon. James put together a team to see how far they could get setting up incident.io in a few days, and invited Eoin to join. "I wasn't convinced to begin with," Eoin says. But getting hands-on changed his mind. "Seeing that helped me understand: okay, this actually makes a bunch of things easier." James saw the gap straight away:
We installed it [incident.io] into Slack and already it was like 100 times better than the internal tooling.
James Bourne, Senior Software Engineer
The hackathon also showed the team what working with incident.io would be like. When they hit a bug mid-hackathon, incident.io had it fixed within half an hour. "We'd never seen a vendor react to us that quickly," Michael says.
Contentful moved incident response over first, then replaced its 10+ year old PagerDuty setup. In the legacy tool every new microservice had needed its own escalation policy, which could add up to half a day of work. Now Contentful's Backstage catalog feeds straight into incident.io’s Catalog. "From day zero of creating a new service, that information gets fed into the Catalog, and any alerts go straight to the team that owns it," James says. Running both systems side by side took the risk out of the switch. The customer experience team went first, and once they'd seen the new setup, "they were so keen to get switched over because they loved the new experience," James says. The rest of engineering followed.
Giving Investigations the full picture
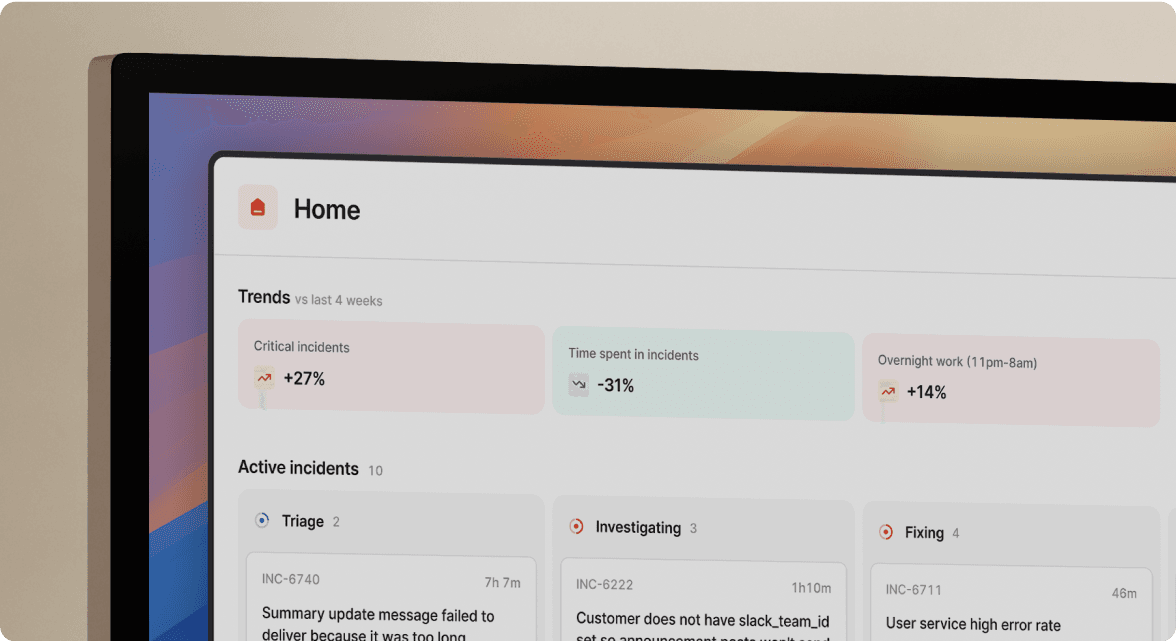
Each step gave incident.io more of Contentful's context: which services exist, who owns them, which alerts are firing and what happened in past incidents. With that context in place, Investigations was a natural next step.
Contentful joined the Investigations beta early and has since built it into its incident response workflow. The last piece of context was monitoring data. As the team consolidated its observability onto Datadog, it connected that too. "When we pulled in that context from Datadog, that's where we saw a huge improvement in the quality of the investigations," James says. "Live telemetry, metrics, traces, logs, everything."
"It’s like having another engineer in there"
Today responders talk to Investigations the way they'd talk to a colleague. "People just say: what's changed recently, dive into our Datadog logs, tell us why this might have happened, are there any correlations?" Eoin says. "It doesn't always get it 100% right, but it's getting better and better over time, and it's learning on our systems."
It's always available, and that changes what one responder can do.
"If there's an incident at seven in the evening and people are commuting home, you could have one engineer lead the whole thing and work with incident.io on the communication side.” says Eoin. “And it still looks as professional as when we would have had multiple people in the past."
Michael says it's the feature he'd miss most.
"Investigations has been an absolute game changer. From catching people up when they join an incident, to finding the PR that triggered an issue, to drafting a status update. It lets you focus on the incident itself rather than the bureaucratic tasks on the side."
Michael Pearce, Senior Engineering Manager
The needle in the haystack
The moment it clicked for James came from a problem that wouldn't normally have counted as an incident. High metric cardinality was driving up costs, and nobody could find where it came from. After hours of digging, James opened an incident anyway so he could put Investigations on it.
It found the cause: a shared code library someone had updated weeks earlier. That new version had been pulled into several services and deployed, and nothing in the original pull request hinted at the problem.
Myself and a staff software engineer had been bashing our heads for at least two hours. Investigations ran for about five minutes and figured it out. We have hundreds of engineers committing across hundreds of repositories. How do you find that needle in the haystack?
James Bourne, Senior Software Engineer
"Tracing all of those dots for a human would have been nearly impossible," James says. "It drilled down into what actually changed in that pull request and connected it together over multiple repositories." It also changed how he thinks about what an incident is: a sudden jump in costs is worth running an incident for.
Trust, earned through outcomes
Eoin's test for any AI in incident response is simple: can he trust it? "The worry everybody has with AI right now is that it's confidently wrong, and then congratulates you when you find out," he says. Contentful's trust in Investigations was built on results, incident after incident.
"When we asked it [incient.io] to do things, it came back with useful information. People just started adopting it naturally, and now it's a critical part of our process, because it's proven itself over time."
Eoin Crowley, VP of Engineering
Out of the corner, into the channel
Investigations works in the incident's Slack channel, so everyone can see what's happening. "Before, a senior responder would go off, do some magic in the background, then come back to the channel with the answer," James says. "For anybody trying to get involved in incident response, that doesn't feel accessible." Now responders can pull data, build a theory and even open a fix as a pull request, all from their phone.
For Eoin, that's the biggest shift: incident response no longer depends on a handful of experts.
It democratizes the thing that only a few specialists used to do. Lots of people can actually be effective in incident response now.
Eoin Crowley, VP of Engineering
Anyone can join an incident, see what's going on and step up to lead it. It used to be about 20 people on call. Now more than 100 engineers have led an incident, and 150 have responded to one.
James sees the difference in post-mortems. "The number of times I've joined a post-mortem and the engineer leading it said: it's my first time." Michael has noticed the same thing: "It shows we've lowered the entry bar. Our teams are less scared of creating an incident if they need to."
Following through on the promise
Eoin cares most about follow-through. Every six weeks, a Claude-powered service pulls incident.io data on SLOs and open follow-up actions for each team, and leadership reviews it with the teams. "Operations is kind of like gardening. You have to keep maintaining it," he says. "Keeping a healthy baseline is way better than every so often stopping everything to pull weeds."
That connects directly to what Contentful promises customers:
We tell customers we have a good process around incident response, root cause analysis and follow-ups. We're confident our system now makes sure we actually do those things, as opposed to just saying it.
Eoin Crowley, VP of Engineering
Peak season is where it shows. "Customers say, we're coming up to Black Friday, we have a retail site, don't be down," Eoin says. "We have more confidence this year than previous years to say: if there are any issues, we'll be on top of it, and we'll respond really, really quickly."
For Eoin, it all comes back to the reliability Contentful's customers are paying for. "Fix it quickly, communicate it well and follow up properly. Those are the three things that underpin what we tell our customers. They can see it in our reliability and availability numbers, but also in how we respond to events."