How we built it: incident.io Status Pages
April 19, 2023 — 9 min read
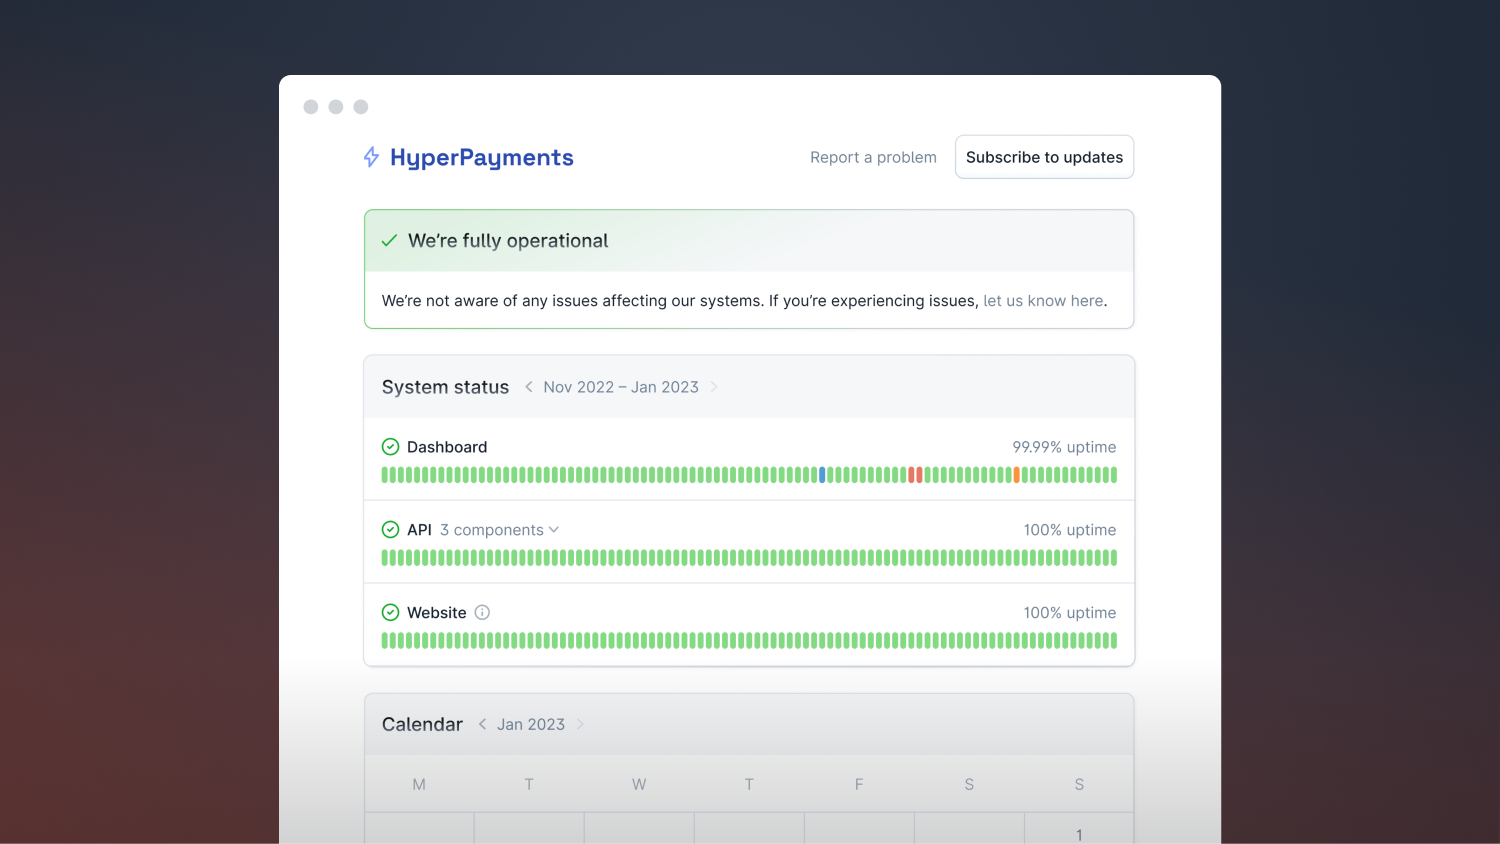
We kicked off 2023 with a new team and a new product to build - Status Pages. We wanted to build a solution we could ship to customers as quickly as possible, while making sure that it’s reliable, fast and beautiful.
Here’s how that process played out over the course of three months.
Defining a tight scope
This isn’t another article about scope-creep, there are plenty of those around!
However, defining what we think is essential from a minimal status page product was still really important to get something launched quickly. Here was our list of non-negotiables for a public-facing status page:
- A status page that loaded quickly and on all devices: The reality is that people will check status pages from their phone, on a poor connection, so we wanted to ensure that they’d be able to do so reliably.
- A solution that was optimized for SEO: Most of the time, people are looking for your status page when they think your product is broken, and they should be able to find it easily.
- Something that handled traffic spikes well: If you’re having a bad day, the last thing you need is your status page going down as well!
- And finally, a status page that looked and felt absolutely beautiful. While this feels insignificant, folks are just more likely to use something if it’s designed well and also very functional.
That’s a lot of work to get through, so we looked for ways to build on top of platforms that can help us ship faster.
Vercel has a solution for that…
That’s quite a lot of requirements, and we really wanted to get this out to our customers as quickly as possible. In general, we try to avoid building software to solve a ‘solved problem’ - we’d far rather leave it to the experts who have a full team dedicated to improving their product.
We had a look around and decided that Vercel had a great platform that would help us with a lot of these challenges. We were also extra psyched because they are shipping new stuff really quickly, and as an added bonus they’re a customer so we know they take incident management seriously 😉.
Cache it, but not too much
Caching is really helpful for making sure that our status pages load quickly and can handle traffic spikes well. However, it’s also really important that when you post an incident to your status page, we deliver that to your customers quickly.
Keeping your customers informed is vital during an incident, and slow updates erode trust and goodwill.
Vercel has a feature called Incremental Static Regeneration (ISR) which lets us get this balance just right.
We tag each call to our backend API with how long it should be cached for, and Vercel caches the response and protects our backend API from traffic surges. For example:
fetch("https://api.incident.io/...", { next: { revalidate: 30 } })
With that option, our backend API will only have to serve two requests a minute, regardless of how many people visit that status page.
Because we’re fetching this data inside React Server Components, Next can also figure out how long that can be cached for.
For example, if a Server Component fetches some data that is cached for 60s and some other data that’s cached for 30s, Next works out that the whole component only needs to be rendered every 30s. Neat!
Cache invalidation
Once a page is in the cache it’ll be super quick, but that leaves two potential problems:
- How does the page get into the cache the first time?
- What happens when the cached page expires?
Luckily, NextJS has this covered, too!
First, using generateStaticParams, we can tell NextJS which status pages exist, and it’ll helpfully pre-build them and put them in the cache for us. We also use on-demand revalidation to add newly-created pages to the cache as soon as they exist.
When the cached value expires, Next will continue to serve the stale value and fetch an updated value in the background. In caching strategy this is often called SWR, or “stale-while-revalidate”.
Live reloading
We’re now able to serve a status page reliably and quickly, but we don’t want to make your customers have to keep hitting refresh to check for updates. It’s 2023, we can do better!
SWR is a data-fetching library which allows for live reloading in a couple of lines of code:
const { data: incident, error, isLoading } = useSWR(
  `/api/incidents/${params.id}`,
  () => getIncident({ id: params.id }),
  {
    refreshInterval: 10000,
    revalidateOnFocus: true,
    fallbackData: incidentFallback,
  },
);
The first thing to remember is that this code is only relevant client-side—on the server side we’re just rendering a static page!
The magic is happening in the options at the end:
refreshIntervaltells SWR to refetch the data from our backend API every 10 seconds.revalidateOnFocusmeans that we’ll also do a refetch whenever you switch back to this tab.
These two options combine to make any updates to a customers status page appear almost instantly:
Finally, fallbackData lets us reuse the API response from server rendering for our first client-side render. This makes it really easy for the client-side app to gracefully enhance the server-rendered page.
Minimising latency
Being able to get data from our backend out to status pages quickly is pretty important. At this point it’s generally quite fast but we wanted to do even better by trying to keep related operations happening physically close to each other.
There are a bunch of network hops involved in building the initial page:
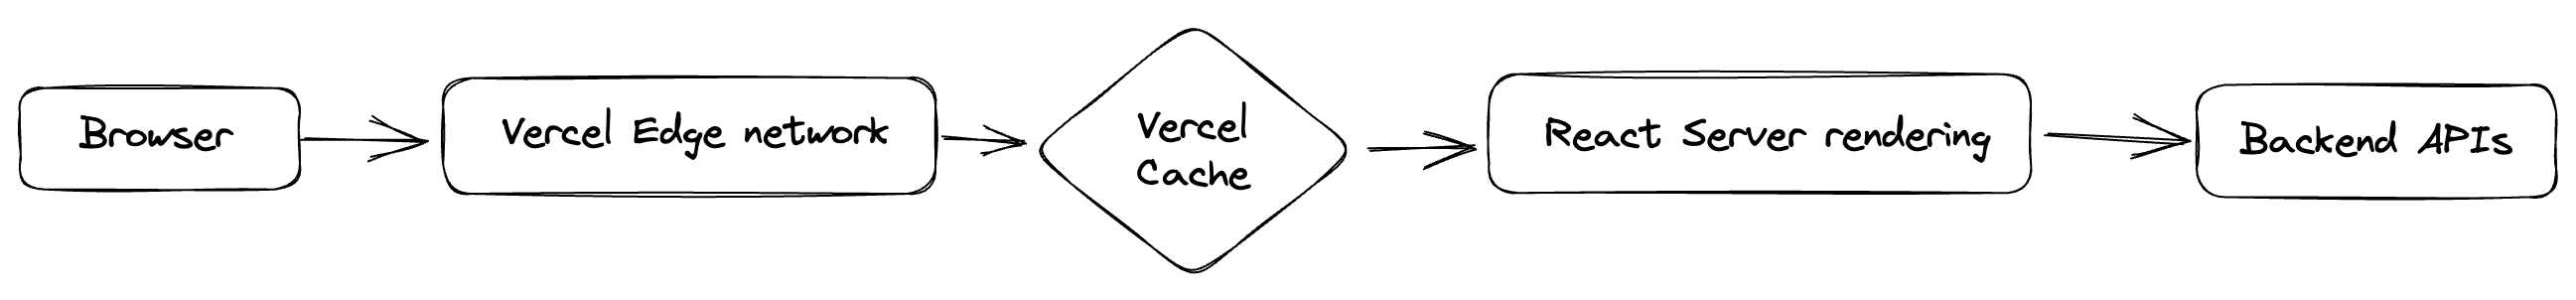
The request runs through Vercel’s Edge network and hopefully returns a cached response from the Vercel Cache. When that needs to be re-rendered, a serverless function runs to generate a new cached value, which talks to our backend APIs.
Vercel sorts a lot of this out for us. Once something makes it into the Vercel Cache, it makes sure it’s distributed around the world so it can be served from as close to the end user as possible.
However, when we’re doing any server-side rendering, we want that to happen as close to our API servers as possible. Luckily, that’s a one-line change to the vercel.json config file:
// vercel.json
{
  "regions": ["dub1"]
}
But what about the live-reloads?
We proxy those through our NextJS app as well, which means they benefit from both the Edge network delivering cached values quickly and fetching of new values happening from next door to our main datacenter in Dublin.
That’s also just a few lines of code in our next.config.js:
{
  ...
  rewrites: [
    {
      source: "/proxy/:path*",
      destination: `${CONFIG.API_URL}/:path*`,
    },
  ],
  ...
}
So…what are the trade-offs?
So far this all sounds pretty simple, and mostly it has been! We could not have built our Status Pages so quickly without using these cutting-edge technologies. However, there are always some rough edges!
The big one is that time formatting is really hard.
Server Rendering dates is *the worst*
— Kent C. Dodds 🌌 (@kentcdodds) April 5, 2023
To gracefully enhance the server-rendered page, React requires that the first client-side render exactly matches what was rendered on the server-side.
Times make that hard in two ways:
- What “now” is changes all the time: With the same input, the server might render “Ongoing for 17s” and the client renders “Ongoing for 18s.”
- Time zones and locales aren’t uniform: Browsers are really good at rendering times in the right format and language. For example the same date might render as “04/19/2023” in New York, but “19/04/2023” in London. Even worse, it might render as “20/04/2023” if it’s 11pm, since that’s 4am UK time.
But thankfully there’s a way around this. We use luxon to make the time zone and locale explicit, and have some linting rules to avoid accidentally using “now” without considering how it can be server rendered.
Just a heads up: we’ll be talking about this in more detail in an upcoming blog post 👀
Wrapping up
There’s of course a lot more behind building a status page product in three months. But we’ve put lots of effort into creating a super-quick set up process, making the page look beautiful, and making publishing updates feel safe and clear.
With that said, there’s much more we’ll be building on this foundation in the coming months.
So be sure to stick around to see what comes next!
Isaac Seymour
Product Engineer
See related articles
We gave cloud agents a phone to QA
Our cloud agents now test mobile pull requests on cloud simulators and leave screenshots and a recording behind. The agent collects the evidence and a person decides whether the change is right.
October 14, 2026
How savepoints quietly throttled our Postgres queue
We 3.5x'd our peak capacity in one of the most performance critical systems we have; here's how we did it, featuring a journey through some Postgres internals.
October 6, 2026
Building Investigations: what it takes to build an AI SRE
We spent the last two years building Investigations, our AI SRE. In this post, go behind the scenes of the work done and why build vs. buy is one of the most important decisions engineering teams are making right now.
October 1, 2026
So good, you’ll break things on purpose
Ready for modern incident management? Book a call with one of our experts today.
We’d love to talk to you about
- All-in-one incident management
- Our unmatched speed of deployment
- Why we’re loved by users and easily adopted
- How we work for the whole organization