Easier alert source set-up
September 2, 2026

We’ve made it a bit easier to set-up your alert sources. Now, teams can directly assign an alert source to their team, which means that every alert coming through the source will be attributed to their team regardless of what's in the alert payload. This was previously possible with setting an alert attribute to an actual team, but this new work makes it much simpler to get started.

With this work, we've also:
- Polished the alert source page, making it more consistent and tucking away some of the more advanced configuration
- Added additional guidance on how to send us alert attributes for more sources
- More of our sources now also have AI suggested attributes

On-call
Enforced notification rules
For customers that leverage our On-call notification policies, you can now select to enforce those rules, not just notify users when they are out of sync. That means, if a user is out of sync with your organization’s policy, we will update their notification rules to meet your set criteria.

Additionally, if you enforce these rules, users won’t be able to delete a required rule or make an alert slower than the required baseline (for example, I cannot set up being notified by mobile app after 5 minutes, if the baseline is 2 minutes).
Responders will still be able to add extra rules or trigger notifications faster than the minimum. The policy will also still alert for users who don't have the notification methods required by the policy rules (for example, if the user hasn’t downloaded their mobile app yet).
Investigations
We now support ClickHouse as a telemetry source
If customers ingest their OTel data into ClickHouse, and have connected ClickHouse in Grafana, we can now discover and query ClickHouse logs, metrics and traces as telemetry sources! We also support Grafana dashboards derived from ClickHouse which should further improve query quality.
As long as customers have connected Grafana to us, and have linked the ClickHouse as a source in Grafana, then we should start discovering the source, which they can then enable. Please check out our public documentation for more details.
Response
Incident templates moved out of alert routes
Previously, the template that determined how an incident got created from an alert lived in the alert route configuration, but now they live in their own settings page.
This has a few advantages:
- One template can be shared by many routes instead of being replicated
- A route can select different templates based on an expression
- Organizations now have a default template which will be used by any route which does not specify one, or when a user declares an incident from an alert manually

Jira Server incident tickets
Jira Service incident tickets now have all the exciting features other issue trackers get in incident tickets, including:
- multiple templates
- match incidents to templates using advanced conditions
- the ticket gets updated as the incident evolves
- updates to the incident are posted back as comments on the ticket
Please see our help docs for more details.
Salesforce incident tickets
We now support Salesforce ServiceCloud Cases as an issue tracker that can be used for incident tickets. Customers can set up templates and sync information bi-directionally.

Additional things to note:
- Core incident fields are synced to Salesforce fields every time they change based on the template.
- Incident updates are posted inside of the connected Salesforce case as internal notes.
- Internal notes and updates from customers get synced back to us and included in Microsoft Teams/Slack.
Platform
Overview pages for Response and On-Call
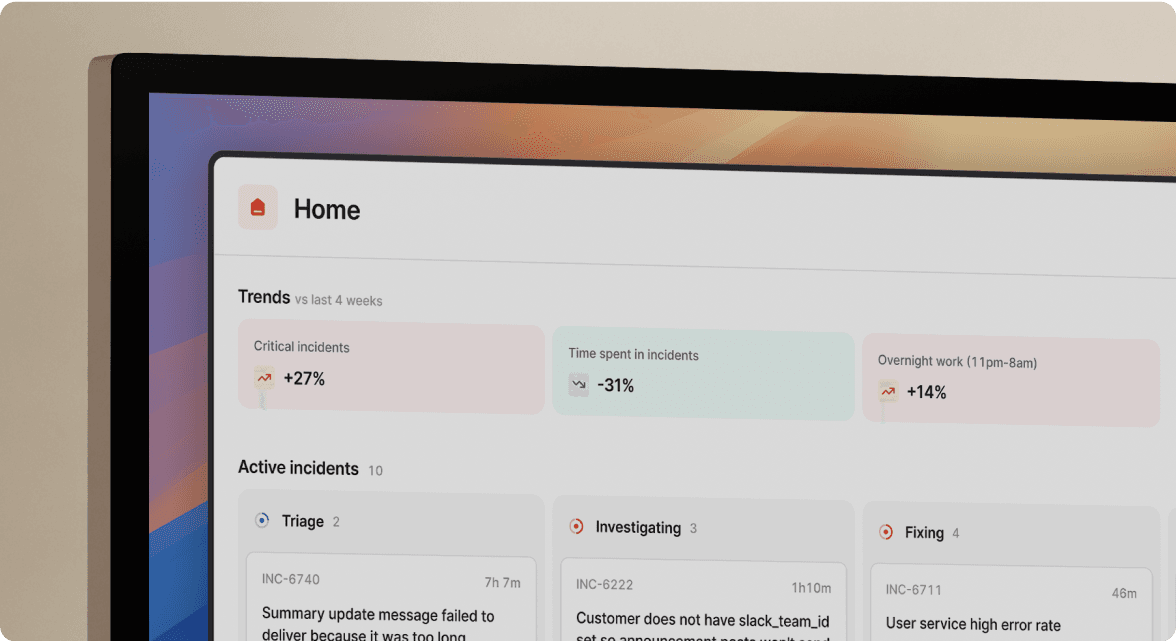
Now clicking "On-Call" or "Response" in the left navigation will take you to an Overview page. These pages are meant to give a high level view of how the product is working to our users, including:
- Relevant policy findings at the top of the overview pages
- Graphs to get a quick lay of the land
- An incident heatmap (now back after some time off!)
- Sparklines for key metrics, such as number of incidents, time spent in incidents, etc.

API
Follow-ups and actions
We've released a V3 version for listing follow-ups and actions in the public API, introducing pagination and a filter on updated at. This is very useful for customers who want to ingest follow-up and action metadata and statuses into third party services like a data warehouse as you can find all the things that have changed since your last sync.
As a bonus, Alerts List now also has an updated_at filter, for customers who want to sync changes to alerts into another system!
Policies
You can now create and manage Policies via the public API or with our Terraform provider to help codify the policies you use to drive your configuration.
You can also now view current and historic policy findings via the public API to do analysis, or sync them to a data warehouse.
Access incident timeline and activity logs
You can now read an incident's timeline over the API, add your own custom items to it, and edit what's on it.
GET /v2/incident_timeline_itemsPOST /v2/incident_timeline_itemsPATCH /v2/incident_timeline_items/{id}
Note that the timeline is a curated narrative of an incident's history - to get the full history, you can also read the full activity log too:
GET /v2/incident_activity_log_entries
API keys with ‘view incident’ access will be able to read the timeline, and editing items requires the ‘incident editor’ role.
Status Pages
You can now add arbitrary links to the footer of your status page
You can now add arbitrary links to the footer of your status page. This is useful for adding, for example, a 'code of conduct' link to your page.
You can configure this in status page Settings → Customization.

Managed status page maintenance through public API
Maintenance windows created through our dashboard default to being automated, which means the status is updated at the specified times without user interaction.
Maintenance windows created through the public API did not have that automation so you had to manually update the status of the status page at the start and end of the window. Now you can opt into managed updates in the public API too by setting automate_maintenance_status.
Please view our API reference for more details.
What else we've shipped
New
- On-callYou can now use Go templating in the incident.io receiver for Prometheus Alertmanager, so you can enrich and customize alerts before they reach incident.io, just as you could with webhook-based integrations.
- On-callWe've added the ability to optionally display an alert status column on the escalation list.
- Status PagesYou can now search and filter your list of status page incidents.
- PlatformThe new left navigation is now fully turned on and can no longer be disabled.
- PlatformOur command line tool inc now supports OAuth
- PlatformYou can now control, at the organization level, whether channel updates sent from the desktop app, plugin, or MCP post under your identity or the bot's identity.
Improvements
- On-callIt's now easier to find how to disconnect a Terraform-synced schedule or escalation path — hovering over the "Synced" badge on a resource now surfaces how to unsync it.
- On-callYou can now send workflow escalation steps at low urgency instead of always paging loudly, and you can ask the AI agent to page someone quietly when you don't want a high-urgency alert.
- On-callThe Snooze button for alerts is now shown consistently across Slack, Teams, mobile, and the dashboard, and remains visible for escalations which have been acknowledged.
- On-callAlerts manually linked to an incident now show up on the incident timeline and postmortem activity log.
- On-callJira alerts can now be resolved directly in incident.io.
- ResponseTest incidents no longer send notifications or channel invites to task assignees during the post-incident flow.
- ResponseWe now show a warning next to the debrief event description field when Outlook Calendar is installed, letting you know Outlook invites are limited to 200 characters and longer descriptions will be shortened.
Bug fixes
- On-callFixed a bug where responding to a cover request from tooltips on a team's schedule page wouldn't open the response drawer, and would leave the page unresponsive.
- On-callFixed an issue where changing the "Request received" date filter while creating a new alert source would crash the page.
- On-callFixed a bug where alert Slack templates with spaces between variables could show garbled replacement characters in the title preview, and in the live alert message itself.
- On-callFixed a bug where the dashboard allowed editing the deduplication key on a Terraform-managed CloudWatch alert source. This is now blocked in the UI, and the key can still be set via Terraform's optional
cloudwatch_options.deduplication_key_path. - ResponseFixed a bug where typing a date into the Custom date range filter would not register keystrokes and show a confusing validation error.
- ResponseFixed a bug where publishing an incident update in Slack could fail with a generic connection error, even though the update text had already finished generating.
- ResponseFixed a bug where attaching a GitHub PR to an incident stream posted a comment linking to a 404 page instead of the stream's actual page.
- ResponseFixed a bug where we kept retrying Zoom co-host updates against meetings that Zoom had already deleted, wasting your account's API quota. We now stop retrying as soon as Zoom confirms a meeting no longer exists.
- ResponseFixed an issue where Zoom co-host settings would silently fail to apply when your Zoom user directory couldn't sync. We now disable the co-host fields and show a clear explanation when this happens.
- ResponseFixed a bug where a single unlicensed Zoom co-host could cause all co-hosts, including fully valid ones, to be removed from a live incident call and never restored for up to 24 hours.
- InvestigationsFixed a bug where a failed telemetry data source discovery would leave the connection screen spinning forever instead of showing the error. We've also fixed testing a data source with "Public internet" selected so it no longer silently routes through an inherited connector, and resolved a healthy connector-routed source getting stuck showing a "needs attention" warning.
- InvestigationsFixed a bug where a database connected through a proxy could pass every connection test but remain stuck in a "needs setup" state, keeping it excluded from Investigations indefinitely.
- InvestigationsFixed an issue where selecting all dashboards would pick the first 100 alphabetically rather than following folder order; selection now respects how dashboards are displayed.
- InvestigationsFixed an issue where the investigation view could show a scoring badge for incidents excluded from scoring, while the timeline correctly showed them as not scored.
- InvestigationsFixed an issue where adding context to an investigation from Slack would post the update under the reporting engineer's name instead of the incident bot's.
- InvestigationsFixed a bug where code blocks in Slack messages from the AI chatbot lost their line breaks, making copied commands invalid.
- InvestigationsFixed an issue where @incident was unable to open GitLab merge requests.
- Status PagesFixed an issue where some status page actions—including publishing a retrospective incident, creating a first incident or maintenance window, deleting a status page incident, and deleting an internal status page—weren't consistently checked against your permissions, so read-only users could attempt them and have them fail. These now correctly show a read-only state up front.

So good, you’ll break things on purpose
Ready for modern incident management? Book a call with one of our experts today.
We’d love to talk to you about
- All-in-one incident management
- Our unmatched speed of deployment
- Why we’re loved by users and easily adopted
- How we work for the whole organization


